Cursos de Datos e IA
Los mismos datos para todos, vengan de Udemy o de Coursera: precio, valoración, duración e idioma. 470 cursos encontrados. Afinar la búsqueda
Model Serving Systems: Containers, APIs & Scalability
"Docker and Model Serving: Deploy ML APIs with FastAPI and ONNX is designed for ML engineers, MLOps practitioners, and backend developers who want to take models from notebooks to production. You'll learn to build Docker containers for ML workloads, design scalable REST APIs with FastAPI, serialize models with ONNX and SavedModel, and deploy with zero-downtime strategies like blue-green and canary releases. The first module covers Docker fundamentals, image optimization, multi-stage builds, secrets management, and Docker Compose for multi-container ML apps. The second module focuses on REST API design with FastAPI, model versioning, input validation with Pydantic, structured logging, and production-grade error handling. The third module teaches scaling strategies — horizontal scaling, async queues, load balancing, batch vs. real-time inference, and latency optimization for high-throughput serving. The final module covers model serialization formats (ONNX, pickle, SavedModel), blue-green and canary deployments, automated rollback, and disaster recovery. By the end of this course, you will: - Build and optimize Docker images for ML models using multi-stage builds and Compose - Design scalable FastAPI endpoints with versioning, validation, and observability - Scale ML inference with async queues, load balancing, and latency optimization - Deploy models with ONNX serialization and zero-downtime blue-green rollbacks"
3. 探索用データを準備する
Google データアナリティクス プロフェッショナル認定プログラムの 3 つめのコースです。このコースでは、1~2 つめのコースで学んだトピックの理解を深めながら、表計算ソフトや SQL などのツールを使って目的に合ったデータを抽出し活用する方法、データの整理と保護の方法など、より実践的なデータアナリティクススキルを身につけるための新しいトピックについても学びます。 また、現職の Google データ アナリストが、最適なツールやリソースを使って、一般的なアナリスト業務を遂行する実践的な方法を指導します。 この認定プログラムを修了すると、エントリーレベルのデータ アナリスト職に応募できるようになります。過去の業務経験は不要です。 このコース修了後の目標は以下の通りです。 - データアナリストが、分析のために収集するデータをどのように決定するかを知る。 - 構造化データや非構造化データ、データ型、データ形式について学ぶ。 - データの信頼性を確保するために、データの中にあるさまざまな種類のバイアスを識別する方法を知る。 - データベースやデータセットに対して、データアナリストがどのように表計算ソフトや SQL を使用するかを学ぶ。 - オープンデータや、データ倫理とデータプライバシーの関連性および重要性を理解する。 - データベースにアクセスし、データを抽出、フィルタリング、並べ替えする方法について理解する。 - データを整理し、安全に管理するためのベストプラクティスを学ぶ。
Building and Optimizing Decision Systems
This course dives into how AI-powered decision systems are designed, modeled, and governed. Built for professionals who turn analytics into real business impact, it guides you through engineering intelligent decision workflows from end to end. You’ll kick off by transforming business challenges into structured decision models designing fast, intuitive data flows and building ethical, human-aware processes that make every choice sharper, clearer, and more confident. Next, you’ll turn raw data into intelligence using forecasting, optimization, and scenario simulations that reveal hidden patterns, anticipate outcomes, and fuel high-impact decisions that propel the business forward. Finally, you’ll elevate trust across your pipelines with explainable AI, dynamic dashboards, and responsible governance, ensuring every decision is transparent, fair, and reliable enough to inspire confidence at every level. By the end of this course, you will be able to: - Analyze business challenges and define structured, data-driven decision problems. - Design scalable, real-time data pipelines that power decision intelligence. - Build predictive and prescriptive models for forecasting and optimization. - Evaluate decision system performance through interactive dashboards. - Apply responsible AI principles to ensure fairness, transparency, and accountability. This course is ideal for data professionals, business analysts, AI engineers, and decision scientists seeking to turn analytics into high-value decisions. Prior experience in data analytics or machine learning will help deepen your learning. Join this course to master intelligent, transparent, and responsible decision system design and learn how to unlock stronger business performance through data-driven intelligence.
Introduction to Deep Learning & Neural Networks with Keras
This course introduces deep learning and neural networks with the Keras library. In this course, you’ll be equipped with foundational knowledge and practical skills to build and evaluate deep learning models. You’ll begin this course by gaining foundational knowledge of neural networks, including forward and backpropagation, gradient descent, and activation functions. You will explore the challenges of deep network training, such as the vanishing gradient problem, and learn how to overcome them using techniques like careful activation function selection. The hands-on labs in this course allow you to build regression and classification models, dive into advanced architectures, such as convolutional neural networks (CNNs), recurrent neural networks (RNNs), transformers, and autoencoders, and utilize pretrained models for enhanced performance. The course culminates in a final project where you’ll apply what you’ve learned to create a model that classifies images and generates captions. By the end of the course, you’ll be able to design, implement, and evaluate a variety of deep learning models and be prepared to take your next steps in the field of machine learning.
Excel Pivot Table Analysis & Visualization
Master Excel Pivot Tables to analyze, summarize, and visualize large datasets efficiently. Learn how to transform raw data into meaningful business insights using dynamic reports, Pivot Charts, and automated reporting techniques. This course provides a practical, hands-on approach to Excel Pivot Tables and data analysis. You’ll learn how to organize and structure data, create Pivot Tables, manage layouts, and generate dynamic reports that simplify complex datasets. Whether you work in finance, operations, HR, analytics, or business reporting, this course helps you streamline analysis workflows and improve reporting efficiency. As you progress, you’ll explore advanced Pivot Table techniques including report filtering, percentage-based analysis, multiple report generation, and dynamic Pivot Charts for visual storytelling. The course also introduces practical problem-solving methods and lookup-based analysis to help learners derive actionable insights from real-world business data. What makes this course unique is its combination of foundational Excel concepts with practical reporting applications used in professional environments. Instead of focusing only on features, the course emphasizes efficient workflows, analytical thinking, and business-focused data interpretation. By the end of the course, you’ll be able to confidently create Pivot Tables, automate reporting tasks, analyze large datasets, build visual reports, and support data-driven decision-making using modern Excel data analysis techniques.
Linear Regression
This course is best suited for individuals who have a technical background in mathematics/statistics/computer science/engineering pursuing a career change to jobs or industries that are data-driven such as finance, retain, tech, healthcare, government and many more. The opportunity is endless. This course is part of the Performance Based Admission courses for the Data Science program. This course will focus on getting you acquainted with the basic ideas behind regression, it provides you with an overview of the basic techniques in regression such as simple and multiple linear regression, and the use of categorical variables. Software Requirements: R Upon successful completion of this course, you will be able to: - Describe the assumptions of the linear regression models. - Compute the least squares estimators using R. - Describe the properties of the least squares estimators. - Use R to fit a linear regression model to a given data set. - Interpret and draw conclusions on the linear regression model. - Use R to perform statistical inference based on the regression models.

Data Analysis Tools
In this course, you will develop and test hypotheses about your data. You will learn a variety of statistical tests, as well as strategies to know how to apply the appropriate one to your specific data and question. Using your choice of two powerful statistical software packages (SAS or Python), you will explore ANOVA, Chi-Square, and Pearson correlation analysis. This course will guide you through basic statistical principles to give you the tools to answer questions you have developed. Throughout the course, you will share your progress with others to gain valuable feedback and provide insight to other learners about their work.
Fundamentals of Visualization with Tableau
In this first course of this specialization, you will discover what data visualization is, and how we can use it to better see and understand data. Using Tableau Public, we’ll examine the fundamental concepts of data visualization and explore the Tableau interface, identifying and applying the various tools Tableau has to offer. By the end of the course you will be able to prepare and import data into Tableau and explain the relationship between data analytics and data visualization. This course is designed for the learner who has never used Tableau before, or who may need a refresher or want to explore Tableau in more depth. No prior technical or analytical background is required. The course will guide you through the steps necessary to create your first visualization from the beginning based on data context, setting the stage for you to advance to the next course in the Specialization.
Clean & Maintain Lists
Transform your email marketing success with data-driven list hygiene practices that boost engagement and deliverability. This Short Course was created to help marketing professionals accomplish systematic list cleaning and performance evaluation. By completing this course, you'll be able to identify and remove problematic contacts, apply industry-standard hygiene rules, and measure the impact of your optimization efforts. By the end of this course, you will be able to: Clean lists to remove redundancies, employing data hygiene practices for improved deliverability and engagement rates Review deliverability KPIs to understand impact and adjust list-maintenance techniques as needed This course is unique because it combines hands-on list cleaning techniques with data-driven evaluation methods, ensuring your hygiene efforts translate to measurable business results. To be successful in this project, you should have a background in email marketing platforms and basic analytics interpretation.
PHI-Ellipses and Fibonacci Trading
Master advanced technical analysis using PHI-Ellipses and Fibonacci trading strategies. Learn how to identify high-probability trades with precision and confidence. This course is designed to help traders move beyond basic indicators and develop a structured, reliable trading approach. You will learn how PHI-Ellipses dynamically adapt to price movements and how to combine them with Fibonacci tools, candlestick patterns, and chart structures. Through practical examples, you will understand how to filter market noise, identify trend reversals, and improve entry and exit timing. The course focuses on combining multiple confirmations to increase trading accuracy while maintaining disciplined risk management. By the end of this course, learners will be able to analyze market trends, apply advanced tools effectively, and build a robust trading strategy suitable for both short-term and long-term trading environments.

Routines in SQL: Stored procedures in SQL Server
Have you thought about creating a query that can be called several times to perform a routine task? Stored procedures offer this with a great advantage of efficiency. This project-based course, "Routines in SQL: Working with stored procedures in MS SQL Server" is intended for intermediate SQL users with some related experiences with SQL and who are willing to advance their knowledge and gain practical experience in MS SQL Server. In this 2-hour project-based course, you will learn how to create stored procedures for different tasks including stored procedures with one input parameter, multiple input parameters, and an output parameter(s). This course is structured in a systematic way and very practical, where you get an option to practice as you progress. This project is unique because it gives you hands-on experience with SQL stored procedures in a business context in which we need to create stored procedures to support the analytics and marketing teams. This project-based course is an intermediate-level course in SQL; therefore, to get the most out of this project, it is essential to understand how to use SQL. Specifically, you should be able to write SQL JOIN statements and work with aggregate functions. If you are comfortable with these SQL concepts, please join me on this wonderful ride! Let’s get our hands dirty!
Cómo combinar y analizar datos complejos
En este curso, aprenderás a usar las ponderaciones de las encuestas para estimar estadísticas descriptivas (como medias y totales) y cantidades más complejas (como parámetros de modelos para regresiones lineales y logísticas). Se explicarán las capacidades de software, haciendo especial hincapié en R®. El curso también abarcará nociones básicas sobre vinculación de registros y búsqueda de coincidencias estadísticas, dos procesos que son cada vez más importantes para combinar datos de fuentes distintas. En el curso, también se exploran los problemas éticos que suscrita la combinación de conjuntos de datos. Es posible que haga falta obtener el consentimiento informado de las personas para que permitan la vinculación de sus datos. Conocerás las diferencias entre los requisitos legales de distintos países.
Apply Generative AI Integration and Deployment Strategies
Learners will analyze Generative AI deployment environments, evaluate platform and vendor options, and apply best practices to integrate, deploy, and manage GenAI systems at scale. By the end of this course, learners will be able to design deployment architectures, assess operational trade-offs, and implement responsible GenAI solutions across real-world use cases. This course equips learners with practical, job-ready skills for integrating Generative AI into production systems. Learners gain a structured understanding of the GenAI development landscape, deployment models, scalability considerations, and vendor evaluation strategies. Through real-world case studies, platform deep dives, and hands-on labs, learners move beyond theory to develop end-to-end deployment competence. What makes this course unique is its balanced focus on strategy, technology, and execution. Instead of treating GenAI deployment as a purely technical exercise, the course emphasizes decision-making, cost management, risk mitigation, and responsible deployment practices. Learners explore leading platforms such as managed foundation model services and inference-optimized frameworks while applying best practices through guided projects. This course is ideal for professionals seeking to operationalize Generative AI solutions reliably, efficiently, and responsibly in modern enterprise environments.

Advanced Pandas
Most Python users pick up just enough pandas to load a CSV and glance at a few rows, then stop there, leaving most of the library's real power untouched. Data scientist Brett Vanderblock built this course to close that gap and take you well past the basics of DataFrame handling. It moves from foundational setup into the cleaning, combining, and scaling techniques that real, messy datasets actually demand. You'll set up and navigate DataFrames, clean and convert messy real-world values, combine and reshape data from multiple sources, and visualize and summarize what you find. You'll also work with tools that extend pandas beyond its core capabilities, including automated data profiling, geospatial analysis, and frameworks built for datasets too large for pandas alone. By the end of this course, you'll be able to take a messy, multi-source dataset and turn it into a clean, well-organized foundation ready for analysis, visualization, or a decision-maker's next move.

GenAI for Technology Consultants
"GenAI for Technology Consultants" is an immersive course designed to equip technology consultants with the knowledge and practical skills necessary to integrate Generative Artificial Intelligence (GenAI) into their daily tasks. Through the use of ChatGPT as the primary GenAI tool, participants will learn how to enhance productivity, foster innovation, and deliver superior value to clients. This course is ideal for both seasoned technology consultants who want to maintain a competitive edge and aspiring professionals who aim to future-proof their skills. Additionally, it caters to business analysts seeking to streamline data analysis and automate report generation, enhancing their ability to make data-driven recommendations. Participants should have a basic understanding of technology consultancy concepts and workflows, including client research, data analysis, and report generation. Experience with consulting tools and methodologies, as well as a fundamental knowledge of GenAI principles, is recommended. A curious mindset and willingness to explore new technologies will greatly benefit learners in this course. By the conclusion of this course, consultants will possess the expertise to effectively incorporate GenAI tools into their consulting repertoire. This course is ideal for both seasoned consultants looking to maintain a competitive edge and aspiring professionals seeking to future-proof their skills. It offers a robust foundation for achieving greater efficiency and innovation in consulting practices.

Foundations of Data Science and Machine Learning with Python
Updated in May 2025. This course now features Coursera Coach! A smarter way to learn with interactive, real-time conversations that help you test your knowledge, challenge assumptions, and deepen your understanding as you progress through the course. Embark on a comprehensive learning journey starting with fundamental Python programming, including installation, variable manipulation, and essential data structures like lists, tuples, and dictionaries. Gain proficiency in numerical computations with NumPy and data manipulation with Pandas. Strengthen your mathematical foundation with key linear algebra concepts vital for machine learning algorithms. Progress to data visualization using Matplotlib and Seaborn, interpreting and presenting data effectively. Develop a strong base in simple linear regression and gradient descent, and explore classification techniques with KNN and logistic regression through hands-on case studies. Dive into advanced machine learning algorithms, including regularization techniques and deep learning foundations, tailored for NLP applications. By course end, you'll have a robust understanding of implementing and optimizing machine learning models for NLP tasks, preparing you for advanced projects and career opportunities. Ideal for aspiring data scientists, machine learning enthusiasts, and professionals specializing in NLP, with basic Python and high school-level math knowledge required.
مشاركة البيانات من خلال فن مؤثرات عرض التصور
هذه هي الدورة التدريبية السادسة في شهادة تحليلات البيانات من Google. ستزودك هذه الدورات بالمهارات اللازمة للتقدم لوظائف محلل البيانات على المستوى التمهيدي. سوف تتعلم كيفية تصور وتقديم نتائج البيانات الخاصة بك عندما تكمل عملية تحليل البيانات. ستوضح لك هذه الدورة التدريبية كيف يمكن أن تساعد تصورات البيانات، مثل لوحات المعلومات المرئية، في إحياء بياناتك. ستستكشف أيضًا Tableau، وهو منصة لتصور البيانات سيساعدك على إنشاء تصورات فعالة لعروضك التقديمية. سيستمر محللو بيانات Google الحاليون بإرشادك وتزويدك بالطرق العملية لإنجاز مهام محلل البيانات الشائعة باستخدام أفضل الأدوات والموارد. سيتم تجهيز المتعلمين الذين يكملون برنامج الشهادة هذا للتقدم لوظائف المستوى التمهيدي كمحللين بيانات. لا تلزم خبرة سابقة. بنهاية هذه الدورة، ستكون قادرًا على: - فحص أهمية تصور البيانات. - تعلم كيفية تكوين سرد مقنع من خلال قصص البيانات. - اكتساب فهم لكيفية استخدام Tableau لإنشاء لوحات معلومات وعوامل تصفية للوحة المعلومات. - اكتشف كيفية استخدام Tableau لإنشاء تصورات فعالة. - اكتشف المبادئ والممارسات المتضمنة في العروض التقديمية الفعالة. - تعرف على كيفية مراعاة القيود المحتملة المرتبطة بالبيانات في عروضك التقديمية. - فهم كيفية تطبيق أفضل الممارسات على الأسئلة والأجوبة مع جمهورك.
Data Validation with Alteryx: Testing and Optimization Tools
Tired of spending hours looking for that one pesky bug that keeps messing up your results? This hands-on Alteryx course teaches you to audit and validate you data input and workflows, to get confidence in you output. You will learn to check input data files for potential errors, detect data loss when combining data streams, and maintain data integrity through joins and aggregations. The course also covers ways to output data into multiple Excel tabs and add custom messages to guide future users of your workflows. By the end, you will be able to add steps to your workflows to minimise errors, ensure consistency and improve the user experience for your colleagues. By taking on the role of somebody tasked with collecting survey results data, you will learn to validate data sources, join and test data streams, keep numeric fields consistent, write data to multi-tab Excel files and implement custom alerts for better workflow management. Learners should already have an understanding of the basic functions in Alteryx such as inputting/outputting data, using joins/unions, and manipulating data with filters, select or formula tools.
Data Processing, Machine Learning, and Model Evaluation
This course teaches you the essential skills required to process and prepare data, model, and evaluate machine learning models. Data processing is a fundamental step in extracting valuable insights from raw data and is crucial in professional data science and machine learning careers. By mastering these techniques, you will enhance your ability to prepare and clean data, build effective machine learning models, and evaluate their performance. These skills are vital for ensuring that your models are accurate, reliable, and ready for deployment in real-world scenarios. The course bridges theory with real-world applications by combining hands-on data processing exercises with machine learning techniques. This approach ensures learners not only understand theoretical concepts but also apply them effectively in practical situations. This course is ideal for aspiring data scientists, machine learning engineers, and professionals looking to strengthen their modeling and evaluation skills. A basic understanding of data science concepts will help, though no advanced experience is required. This course is part two of a three-course Specialization designed to provide a comprehensive learning pathway in this subject area. While it delivers standalone value and practical skills, learners seeking a more integrated and in-depth progression may benefit from completing the full Specialization. From CompTIA DataX Study Guide Copyright © 2024 by John Wiley & Sons, Inc. All rights, including for text and data mining, AI training, and similar technologies, are reserved. Used by arrangement with John Wiley & Sons, Inc.
Seaborn: Visualizing Basics to Advanced Statistical Plots
Data visualization is a powerful tool for exploring and communicating insights from data effectively. Seaborn, a Python visualization library built on top of Matplotlib, offers a wide range of features for creating attractive and informative statistical plots. This course provides a comprehensive overview of Seaborn, covering basic plotting techniques as well as advanced statistical visualizations. Participants will learn how to leverage Seaborn to visualize data distributions, relationships, and patterns, enabling them to convey complex information visually with confidence. Data visualization is a powerful tool for exploring and communicating insights from data effectively. Seaborn, a Python visualization library built on top of Matplotlib, offers a wide range of features for creating attractive and informative statistical plots. This course provides a comprehensive overview of Seaborn, covering basic plotting techniques as well as advanced statistical visualizations. Participants will learn how to leverage Seaborn to visualize data distributions, relationships, and patterns, enabling them to convey complex information visually with confidence. Participants should have a basic understanding of Python programming and fundamental data visualization concepts before enrolling in this course. Familiarity with Python's data manipulation libraries such as Pandas, and an introductory knowledge of Matplotlib, will be beneficial. This foundational knowledge will enable learners to quickly grasp Seaborn's functionalities and apply them effectively in their data visualization tasks. By the end of this course, learners will be equipped to explain the critical role of data visualization in data analysis and interpretation. They will gain practical skills in creating basic plots using Seaborn to visualize data distributions and relationships. Additionally, learners will explore advanced statistical plots for deeper data analysis and develop the ability to customize and enhance Seaborn visualizations, ensuring their data stories are communicated clearly and impactfully.
R البرمجة باستخدام لغة
ستتعلم في هذه الدورة كيفية البرمجة بلغة R وكيفية استخدامها لتحليل البيانات بصورة فعالة. ستتعلم كيفية تثبيت البرامج اللازمة لبيئة البرمجة الإحصائية وتكوينها وكيفية وصف مفاهيم لغة البرمجة العامة إذ يتم تطبيقها بلغة إحصائية عالية المستوى. تتناول الدورة المشكلات العملية في الحوسبة الإحصائية التي تشمل البرمجة في لغة R، وقراءة البيانات في لغة البرمجة R، والوصول إلى حزم R، وكتابة دوال R، وتصحيح الأخطاء، وتحديد التعليمات البرمجية R، وتنظيم التعليمات البرمجية R والتعليق عليها. ستعرض الموضوعات في تحليل البيانات الإحصائية أمثلة عملية.
Automate R scripts with GitHub Actions: Deploy a model
Did you know you can automate R scripts to facilitate model deployment and enhance workflow efficiency in healthcare analytics? This Guided Project is designed for data scientists, healthcare analysts, and professionals in healthcare technology who want to harness the power of automation in R. In this 2-hour project-based course, you will learn how to deploy a machine learning model using R programming language and GitHub Actions, enabling seamless integration and automation of predictive tasks. To support the model deployment, you will also automate access to data in Google Sheets and send automated emails through a Google Service Account. To achieve this, you will use a readmission model, write an R script for prediction, configure Google Sheets, Gmail, and GitHub Actions for automation, and deliver actionable insights for healthcare providers. This project is unique because it combines technical skills with real-world applications, preparing you to tackle complex challenges in data analytics. Prior knowledge in R programming, including data manipulation (using the dplyr and tidyr packages), programming concepts (functions and control structures), GitHub repositories for code management, and basic command line use is recommended to maximize your learning experience.
Build & Analyze Your Data Lakehouse
The modern data landscape demands professionals who can seamlessly bridge the gap between data lakes and data warehouses. This course transforms your ability to architect, implement, and optimize lakehouse platforms that deliver both flexibility and performance. This Short Course was created to help data engineering professionals accomplish scalable data platform implementation using advanced SQL and lakehouse patterns. By completing this course, you'll be able to register massive file-based datasets as queryable external tables, make informed decisions between Delta Lake, Iceberg, and Hudi formats, and automate robust data ingestion pipelines that keep your warehouse synchronized with your lake. By the end of this course, you will be able to: - Apply configurations to register file-based datasets as external tables - Analyze the technical capabilities of different open-source table formats - Create a data ingestion pipeline within a lakehouse architecture This course is unique because it combines hands-on SQL implementation with strategic architectural decision-making, giving you both the technical skills and analytical framework needed for enterprise-scale data platforms. To be successful in this course, you should have a background in SQL, data warehousing concepts, and distributed systems fundamentals.
Data Collection and Integration
The "Data Collection and Integration" course provides students with comprehensive techniques for gathering data from diverse sources, including files, relational databases, web pages, and APIs. Participants will gain practical experience in collecting and integrating data for further processing and analysis. The course emphasizes the utilization of appropriate tools and packages, such as Pandas, Beautiful Soup, and SQL, to effectively handle real-life datasets and address data integration challenges.

Building a Machine Learning Solution
Welcome to Building a Machine Learning Solution, where you'll journey through the complete lifecycle of a machine learning project. This capstone course covers critical steps from problem definition to deployment and maintenance. You'll learn to define clear problem statements, collect and preprocess data, perform exploratory data analysis (EDA), and engineer features to enhance model performance. The course guides you in selecting and implementing appropriate models, comparing classical machine learning, deep learning, and generative AI approaches. Emphasizing real-world considerations, you'll address scalability, interpretability, and ethical implications. You'll gain hands-on experience with tools like scikit-learn, TensorFlow, PyTorch, and more, ensuring you can deploy and monitor models effectively. By the end of this course, you'll be equipped to build end-to-end ML solutions that transform data into actionable insights, making informed decisions at each stage of development.
Applied Natural Language Processing in Engineering Part 1
Welcome to this course on applied natural language processing in engineering. This course is designed to provide you with an in-depth understanding of NLP, a pivotal area of artificial intelligence that empowers computers to comprehend, interpret, and generate human language. Throughout this course, you will explore a wide range of topics, from fundamental NLP tasks like text classification and Named Entity Recognition (NER) to advanced techniques in neural machine translation and optimization methods critical for machine learning. We will delve into the complexities of teaching language to machines, addressing challenges like ambiguity, grammar, and cultural nuances. By the end of this part 1 course, you will have a foundational understanding of how modern NLP systems work - particularly those involving machine learning and deep learning. These topics will equip you to build, analyze and improve NLP systems across many applications.
Transform Financial Data: Recall & Import
Financial analysts spend hours manually reformatting data feeds—time that could be spent on analysis. This intermediate course teaches you to recognize data structures and automate transformations using Power Query, turning repetitive cleanup into one-click refreshes. You'll start by classifying structured, semi-structured, and unstructured data across typical financial sources—understanding how each format affects accuracy, governance, and reporting workflows. Then you'll master Power Query to import JSON feeds, flatten nested hierarchies, and create automated refresh pipelines that keep dashboards current without manual intervention. Through short videos, practical readings, and hands-on labs, you'll connect data concepts to daily analyst work—from explaining structure types in governance meetings to building repeatable transformation workflows. Real-world examples from firms like PwC and EY show how data literacy and automation drive accuracy, efficiency, and compliance. By the end, you'll transform messy JSON into clean tables, automate refresh workflows, and build the foundation for reliable, efficient financial reporting that scales.

Master Machine Learning with TensorFlow: Basics to Advanced
Build a strong foundation in machine learning, deep learning, and TensorFlow through a structured, hands-on learning experience that takes you from core concepts to practical model development. In this course, you will learn how machine learning works, explore real-world applications across industries, and set up a professional Python development environment using Jupyter Notebook, Anaconda, and essential data science libraries. As you progress, you will develop practical skills in data wrangling with Pandas, numerical computing with NumPy, and data visualization using Matplotlib and Seaborn. You will also learn how to preprocess datasets, engineer features, and build classical machine learning models with Scikit-learn before advancing to deep learning with TensorFlow. Through hands-on exercises and real-world datasets, you will train, optimize, and evaluate regression models and neural networks, including image classification with the MNIST dataset. Designed for beginners entering machine learning as well as professionals looking to strengthen their TensorFlow knowledge, this course combines clear explanations with coding practice, case studies, and assessments that reinforce every stage of the machine learning workflow. By the end of the course, you will be able to confidently preprocess data, build and evaluate machine learning and deep learning models, visualize insights, and apply industry-standard tools to solve real-world problems.
Data Analytics with Skills.AI: Create Data Visualizations
In this 1-hour long project-based course, you will learn how to Navigate and register on the Skills.AI platform effectively, Create infographics and visualize data using AI tools, and Interact with visual reports for enhanced insights.
NoSQL Databases: Analyze & Implement Scalable Systems
Build the skills to analyze, apply, and implement scalable data systems using NoSQL databases, Apache Oozie, Apache Storm, and Apache Mahout. You’ll begin by exploring the origins and benefits of NoSQL, including schema flexibility, diverse data types, data versioning, and the role of NoSQL in managing large-scale, unstructured data. You’ll also compare ACID and BASE consistency models and apply consistency principles to application development. Next, you’ll design and schedule big data workflows with Apache Oozie using Hive actions, control nodes, coordinators, and workflow applications. You’ll then use Apache Storm for real-time stream processing, working with topologies, stream groupings, tasks, workers, Zookeeper, deployment, parallelism, and reliability mechanisms. Finally, you’ll apply Apache Mahout to scalable machine learning workflows. You’ll design recommendation systems, use classification and clustering techniques, evaluate model performance, and work with Canopy, Naïve Bayes, KMeans, and Logistic Regression. Designed for aspiring data engineers, developers, and analysts, this course uniquely connects database design, workflow orchestration, real-time processing, and machine learning in one structured journey. Enroll to gain practical skills for building scalable, fault-tolerant, and intelligent big data solutions.
أساسيات تحليل البيانات باستخدام بايثون وباندا
في هذه الدورة التدريبية القائمة على المشروع والتي تستغرق ساعة ونصف تقريباً ستتعلم كيفية تحليل البيانات باستخدام لغة البرمجة بايثون. ستتعرف على مكتبات تحليل البيانات والتعامل مع الأرقام في بايثون، كما ستتعلم كيفية تنظيف البيانات وترتيبها لتهيئتها للتحليل وكيفية الحصول على إجابات للأسئلة المتعلقة بالبيانات التي لديك. سنقوم باستخدام جوبيتر نوتبوك لكتابة الأكواد وتنفيذها والحصول على رسومات بيانية تمثل البيانات. لا يوجد متطلبات سابقة للبدء بالمشروع حيث أن هذا المشروع هو للمبتدئين تماما في تحليل البيانات باستخدام بايثون وسيكون هناك شرح مفصل لكل خطوة من الخطوات التي ستقوم بها لإتمامه.
Bracketology with Google Machine Learning
This is a self-paced lab that takes place in the Google Cloud console. In this lab you use Machine Learning (ML) to analyze the public NCAA dataset and predict NCAA tournament brackets.
Crystal Reports: SQL Statements and Complex Formulas
In this course, you'll continue developing your data-reporting skills in Crystal Reports by using Structured Query Language (SQL) statements to create and summarize report data, as well as create joins and subqueries. You'll also create more complex formulas by working with loops and arrays. These tools and techniques provide you with even greater control over how your data is presented. This is the third course in a multi-course Specialization. All of the courses in this Specialization require that you have SAP Crystal Reports 2020 installed. You also need to have an installation of Office 2019 apps or later, particularly Access. The course setup instructions provided in the first course go into more detail about the hardware and software requirements.
Analyze Employee Performance Using Excel Pivot Tables
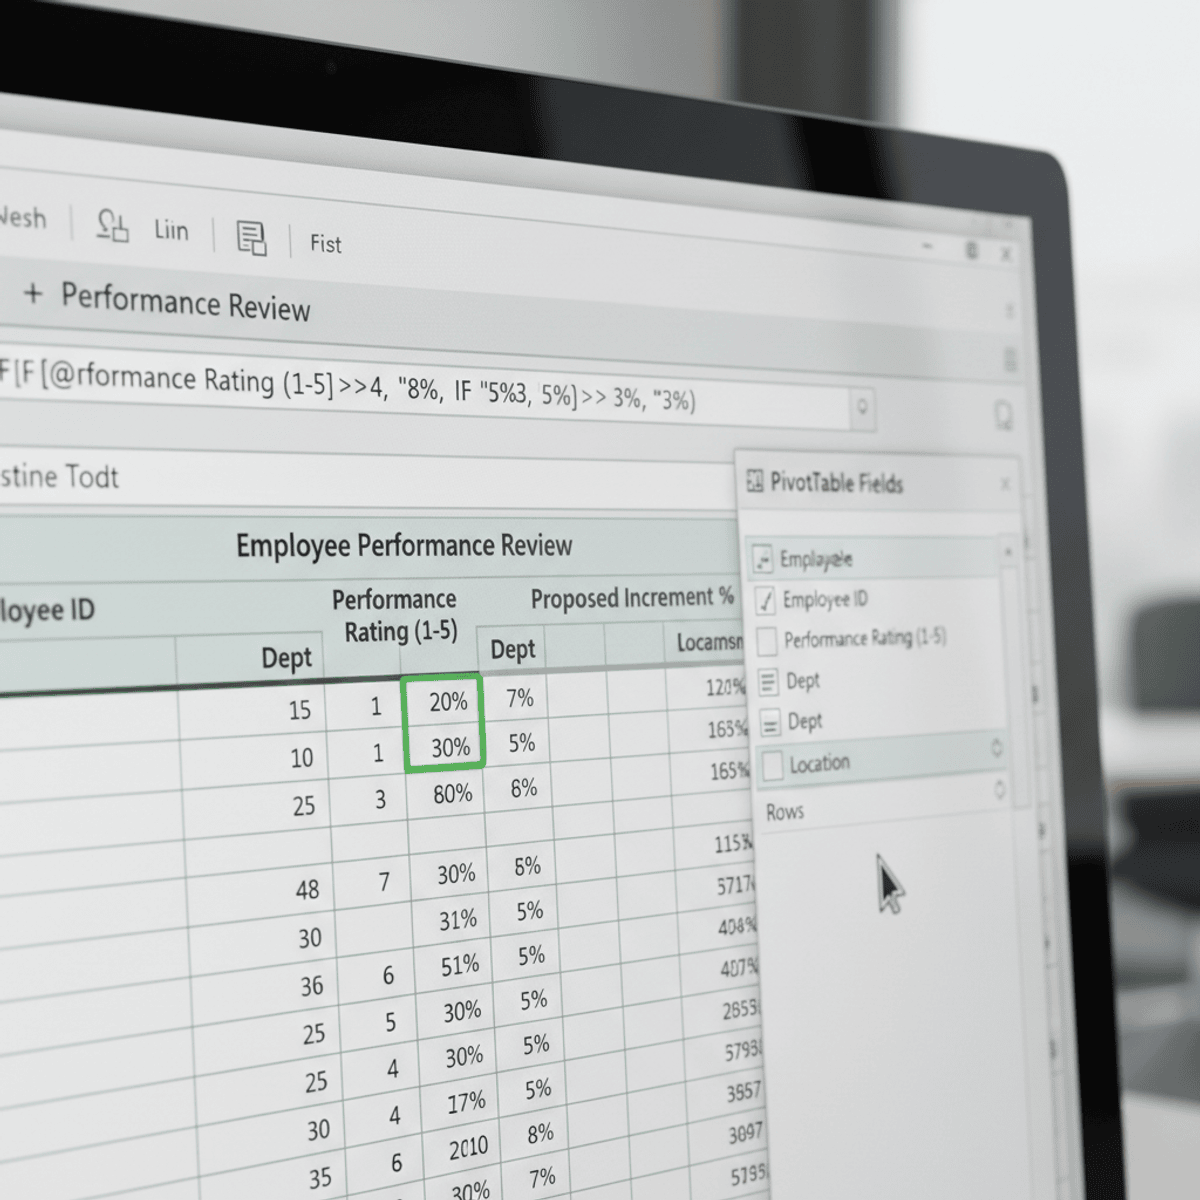
By the end of this course, learners will be able to analyze employee performance data, calculate performance-based increments, build and refine Pivot Tables, compare results across departments and locations, and evaluate budget deviations to support data-driven decisions. This course provides a practical, hands-on case study focused on employee performance ratings, designed to help learners move beyond basic Excel functions into real-world analytical thinking. Learners will begin by understanding and preparing a structured dataset, applying formulas to compute performance metrics, and visualizing data relationships. The course then guides learners through constructing Pivot Tables to answer business questions, perform comparative analysis, and uncover meaningful performance trends. What makes this course unique is its end-to-end, scenario-based approach. Instead of isolated Excel features, learners work through a single, coherent business case that mirrors real workplace analysis. Each step builds progressively, reinforcing analytical skills and practical problem-solving. Upon completion, learners will gain job-relevant Excel skills, improved confidence in performance analysis, and the ability to transform raw HR data into actionable insights—skills directly applicable to roles in business analysis, HR analytics, and operations.
Data Science Decisions in Time: Using Causal Information
This is the fourth course in the specialization and is aimed at those with basic knowledge of statistics, probability and linear algebra. It will prove to be especially interesting for those with datasets that are being used to make decisions: either business, medical, or technology based.
Natural Language Processing on Google Cloud
This course introduces the products and solutions to solve NLP problems on Google Cloud. Additionally, it explores the processes, techniques, and tools to develop an NLP project with neural networks by using Vertex AI and TensorFlow. - Recognize the NLP products and the solutions on Google Cloud. - Create an end-to-end NLP workflow by using AutoML with Vertex AI. - Build different NLP models including DNN, RNN, LSTM, and GRU by using TensorFlow. - Recognize advanced NLP models such as encoder-decoder, attention mechanism, transformers, and BERT. - Understand transfer learning and apply pre-trained models to solve NLP problems. Prerequisites: Basic SQL, familiarity with Python and TensorFlow

GenAI for Risk Managers: Advanced Risk Analysis Techniques
In this course, you’ll discover how Generative AI can enhance risk detection, automate monitoring, and improve decision-making. Through hands-on projects and real-world case studies, you’ll gain practical expertise to apply AI-driven strategies in complex risk environments. Whether you’re a risk professional or business leader, this course will equip you with the tools to transform your approach to risk management. This course is designed for experienced professionals at the forefront of risk management, quantitative analysis, and AI-driven modeling. Whether you're a Senior Risk Analyst or Manager looking to enhance predictive insights, a Quantitative Risk Specialist refining complex risk models, or an AI Risk Model Developer integrating GenAI into risk assessment frameworks, this course offers advanced methodologies to elevate your expertise. Enterprise Risk Architecture Specialists will gain insights into multi-source data integration, while Advanced Risk Analytics Professionals will explore cutting-edge AI-driven techniques to automate risk detection and enhance decision-making in high-stakes environments. To ensure you gain the most from this course, we recommend a solid foundation in risk analysis and AI-driven methodologies. Learners should have completed GenAI for Risk Managers: Essentials (or possess equivalent experience), along with a working knowledge of risk modeling, quantitative analysis, and fundamental machine learning concepts. Familiarity with established risk management frameworks and tools will further enhance your ability to apply advanced GenAI techniques effectively. This course is designed for professionals ready to push the boundaries of AI-driven risk strategies. By the end of this course, you will have the skills and confidence to integrate Generative AI into your risk management strategies effectively. You’ll be equipped with advanced techniques for risk detection, scenario modeling, and real-time monitoring, enabling you to make data-driven decisions with greater precision. As AI continues to transform the risk landscape, your ability to leverage GenAI will position you at the forefront of innovation in risk management.
Advanced AI Techniques for the Supply Chain
In this course, we’ll learn about more advanced machine learning methods that are used to tackle problems in the supply chain. We’ll start with an overview of the different ML paradigms (regression/classification) and where the latest models fit into these breakdowns. Then, we’ll dive deeper into some of the specific techniques and use cases such as using neural networks to predict product demand and random forests to classify products. An important part to using these models is understanding their assumptions and required preprocessing steps. We’ll end with a project incorporating advanced techniques with an image classification problem to find faulty products coming out of a machine.
Extract, Transform, and Load Data
This course is designed for business and data professional seeking to learn the first technical phase of the data science process known as Extract, Transform and Load or ETL. Learners will be taught how to collect data from multiple sources so it is available to be transformed and cleaned and then will dive into collected data sets to prepare and clean data so that it can later be loaded into its ultimate destination. In the conclusion of the course learners will load data into its ultimate destination so that it can be analyzed and modeled. The typical student in this course will have experience working with data and aptitude with computer programming.
Optimize ML Models: Hyperparameter Tuning
Optimize ML Models: Hyperparameter Tuning gives you the practical skills to move from “good enough” models to models that perform reliably at scale. You’ll learn how default hyperparameters shape model behavior, how computational complexity affects training cost, and why structured tuning methods outperform guesswork. Through short videos, hands-on practice, and a guided GridSearchCV project, you’ll build a complete workflow for selecting, evaluating, and explaining tuned model configurations. By the end of the course, you’ll know how to design effective search spaces, run systematic tuning experiments, interpret cross-validated results, and save tuned parameters for real ML pipelines—all essential skills for modern machine learning and AI roles.
Code Free Data Science
The Code Free Data Science class is designed for learners seeking to gain or expand their knowledge in the area of Data Science. Participants will receive the basic training in effective predictive analytic approaches accompanying the growing discipline of Data Science without any programming requirements. Machine Learning methods will be presented by utilizing the KNIME Analytics Platform to discover patterns and relationships in data. Predicting future trends and behaviors allows for proactive, data-driven decisions. During the class learners will acquire new skills to apply predictive algorithms to real data, evaluate, validate and interpret the results without any pre requisites for any kind of programming. Participants will gain the essential skills to design, build, verify and test predictive models. You Will Learn • How to design Data Science workflows without any programming involved • Essential Data Science skills to design, build, test and evaluate predictive models • Data Manipulation, preparation and Classification and clustering methods • Ways to apply Data Science algorithms to real data and evaluate and interpret the results
Draft Employment Contract Pack
What happens when a single missing clause in an employment contract exposes your company to six-figure litigation? This Short Course was created to help Legal professionals accomplish the full drafting cycle of a signature-ready employment contract pack. By the end of this course, you will be able to: - Draft jurisdiction-appropriate at-will employment language that balances employer flexibility with statutory notice requirements. - Insert equity grant provisions, including vesting schedule and acceleration triggers, into the offer letter template. - Evaluate the enforceability of the proposed non-compete clause against the governing jurisdiction's current legal standards. This course is unique because it bridges statutory compliance with practical drafting — combining real fact patterns, equity mechanics, and evolving state non-compete law into one cohesive deliverable. To be successful in this course, you should have a background in foundational contract law and basic employment law principles at the CB2 mid-level.
Analyze Box Office Data with Seaborn and Python
Welcome to this project-based course on Analyzing Box Office Data with Seaborn and Python. In this course, you will be working with the The Movie Database (TMDB) Box Office Prediction data set. The motion picture industry is raking in more revenue than ever with its expansive growth the world over. Can we build models to accurately predict movie revenue? Could the results from these models be used to further increase revenue? We try to answer these questions by way of exploratory data analysis (EDA) in this project and the next. The statistical data visualization libraries Seaborn and Plotly will be our workhorses to generate interactive, publication-quality graphs. By the end of this course, you will be able to produce data visualizations in Python with Seaborn, and apply graphical techniques used in exploratory data analysis (EDA). This course runs on Coursera's hands-on project platform called Rhyme. On Rhyme, you do projects in a hands-on manner in your browser. You will get instant access to pre-configured cloud desktops containing all of the software and data you need for the project. Everything is already set up directly in your internet browser so you can just focus on learning. For this project, you’ll get instant access to a cloud desktop with Python, Jupyter, and scikit-learn pre-installed. Notes: - You will be able to access the cloud desktop 5 times. However, you will be able to access instructions videos as many times as you want. - This course works best for learners who are based in the North America region. We’re currently working on providing the same experience in other regions.
Data Storage and Management for Big Data
This course provides a comprehensive overview of data storage and management approaches for big data. Learners will explore structured, semi-structured, and unstructured data formats, compare SQL and NoSQL database technologies, and implement data lakes and data warehouses. The course includes working with various file formats and understanding the differences between batch and real-time processing approaches. Course Learning Objectives: By the end of this course, you will be able to: - Compare and implement SQL and NoSQL database solutions for different big data scenarios - Work effectively with structured, semi-structured, and unstructured data formats - Design and implement data lakes and data warehouses for big data workloads - Build data pipelines using ETL and ELT approaches with Azure Data Factory - Differentiate between batch and real-time processing methodologies and implement appropriate solutions
Rethink How You Decide with AI
The right questions make AI a valuable tool for decision-making. "Rethink How You Decide with AI" teaches you how to use AI as a thought partner, allowing you to make more intentional, informed decisions. Through guided activities, reflection, and hands-on AI exploration, you'll examine the habits, assumptions, and patterns that shape your choices. You'll identify the constraints and tradeoffs behind real decisions, compare different approaches to setting priorities, and practice using AI to generate perspectives, challenge assumptions, and uncover blind spots. Your goal isn’t finding the "perfect answer," it’s developing a flexible decision-making process that evolves with you. Along the way, you'll learn how to use generative AI to stress-test ideas, evaluate alternatives, and strengthen your reasoning while maintaining ownership of your decisions. By the end of this course, you’ll have a personalized system that supports your decision-making, allowing you to move forward with your ideas with great clarity, confidence, and intention. This is the third course in the "Applied AI: Data Analysis, Workflows, and Decisions" series, a three-course series on practical ways to integrate AI into your personal and professional routines.
Microsoft Fabric Analytics Engineer: DP-600 Exam Prep
Microsoft Fabric represents a paradigm shift in enterprise analytics, unifying data engineering, data warehousing, and business intelligence into a single, cohesive SaaS ecosystem. This course is your definitive guide to mastering that ecosystem, moving beyond theoretical concepts to the practical implementation required to earn the Fabric Analytics Engineer Associate certification. As a Fabric Analytics Engineer Associate, you are expected to demonstrate subject matter expertise in designing, building, and deploying enterprise-scale analytics solutions while confidently querying and analyzing data using SQL, KQL, and DAX. This program is purpose-built to help you master those competencies with clarity and precision. You will navigate the full Microsoft Fabric ecosystem, including OneLake, Lakehouse, Warehouse, Apache Spark, Data Factory, Dataflows Gen2, Real-Time Intelligence, Semantic Models, and Power BI. The course emphasizes how these components integrate into a unified, high-performance analytics architecture. From orchestrating robust data ingestion pipelines and Spark transformations to structuring Medallion architectures powered by Delta Lake, you will develop scalable data foundations. You will then advance into analytical engineering, implementing T-SQL in Warehouses, designing real-time intelligence solutions using Eventhouse and KQL, and building optimized semantic models using advanced DAX techniques. Beyond implementation, the course reinforces enterprise-grade standards. You will configure security frameworks, including RLS and OLS, integrate governance through Microsoft Purview, monitor capacity and performance metrics, and align deployments with compliance and operational best practices. By the end of this course, you will be equipped to: - Design enterprise-grade analytics architectures using Microsoft Fabric components. - Develop scalable data ingestion and transformation workflows across Lakehouse, Warehouse, Spark, and Real-Time workloads. - Analyze data using SQL, KQL, and DAX in structured and streaming environments. - Construct optimized semantic models using appropriate storage and performance strategies. - Implement security and governance frameworks aligned with enterprise standards. Designed for analytics engineers, data professionals, and BI architects seeking to validate and elevate their expertise, this course blends certification precision with real-world architectural depth. Elevate your capabilities. Prove your readiness. Become a certified Microsoft Fabric Analytics Engineer.
Predictive Analytics with SPSS: Analyze & Apply
Master predictive analytics with SPSS through a structured progression from data management and descriptive statistics to correlation, linear and multiple regression, logistic regression, and multinomial regression. You will learn to import and organize datasets, calculate mean and standard deviation, create scatter plots, examine relationships between variables, construct predictive models, refine predictors, calculate predicted values, and interpret coefficients, significance levels, odds ratios, model-fitting results, and parameter estimates. Designed for students, researchers, and professionals who want to use SPSS for research, business, academic, health, psychology, or financial analysis, this course connects statistical concepts with practical decision-making. Guided SPSS demonstrations and hands-on case studies involving heart pulse, student test scores, copper expansion, energy consumption, debt assessment, credit card data, smoking preferences, and health outcomes help you apply each technique to varied datasets. By the end of the course, you will be able to select and apply appropriate predictive modeling techniques, evaluate predictors, interpret SPSS regression outputs, validate results, and turn raw data into meaningful insights. Its step-by-step design, diverse case-based practice, and balance of statistical interpretation with software application make it a practical path from SPSS fundamentals to advanced regression analysis.
Social Network Analysis
This course is designed to quite literally ‘make a science’ out of something at the heart of society: social networks. Humans are natural network scientists, as we compute new network configurations all the time, almost unaware, when thinking about friends and family (which are particular forms of social networks), about colleagues and organizational relations (other, overlapping network structures), and about how to navigate delicate or opportunistic network configurations to save guard or advance in our social standing (with society being one big social network itself). While such network structures always existed, computational social science has helped to reveal and to study them more systematically. In the first part of the course we focus on network structure. This looks as static snapshots of networks, which can be intricate and reveal important aspects of social systems. In our hands-on lab, you will also visualize and analyze a network with a software yourself, which will help to appreciate the complexity social networks can take on. During the second part of the course, we will look at how networks evolve in time. We ask how we can predict what kind of network will form and if and how we could influence network dynamics.
Voice AI: Introduction to Building Voice Applications
Build Practical Voice Apps: From Basics to Implementation is a beginner-level course designed to help developers create voice applications that users actually want to use. As voice AI transforms industries from healthcare to retail, the demand for skilled voice application developers continues to grow. This course provides hands-on experience with the core technologies—speech recognition, natural language processing, and text-to-speech—while emphasizing real-world implementation challenges and user experience design. Through practical projects, real-world case studies from companies like Deepgram and VAPI AI, and comprehensive testing strategies, you'll learn to build voice applications that solve genuine business problems. The course covers everything from choosing the right APIs and optimizing for different environments to integrating with existing systems and deploying production-ready solutions. Whether you're adding voice features to existing applications or creating entirely new voice-first experiences, this course gives you the practical skills and strategic thinking needed to succeed in the rapidly evolving voice AI landscape.
Machine Learning in the Enterprise - Français
Ce cours présente une approche pratique du workflow de ML avec une étude de cas dans laquelle une équipe est confrontée à plusieurs exigences métier et cas d'utilisation de ML. Cette équipe doit comprendre quels outils sont nécessaires pour gérer et gouverner les données, et trouver la meilleure approche pour les prétraiter. On présente à cette équipe trois options de création de modèles de ML pour deux cas d'utilisation spécifiques. Ce cours explique pourquoi l'équipe tire parti des avantages d'AutoML, de BigQuery ML ou de l'entraînement personnalisé pour atteindre ses objectifs.